Running gmx_MMPBSA
Before running gmx_MMPBSA
gmx_MMPBSA requires minimal preprocessing of the input structure and trajectory files. Before running gmx_MMPBSA, complete the following checks.
Check the structure supplied with -cs, -rs, or -ls
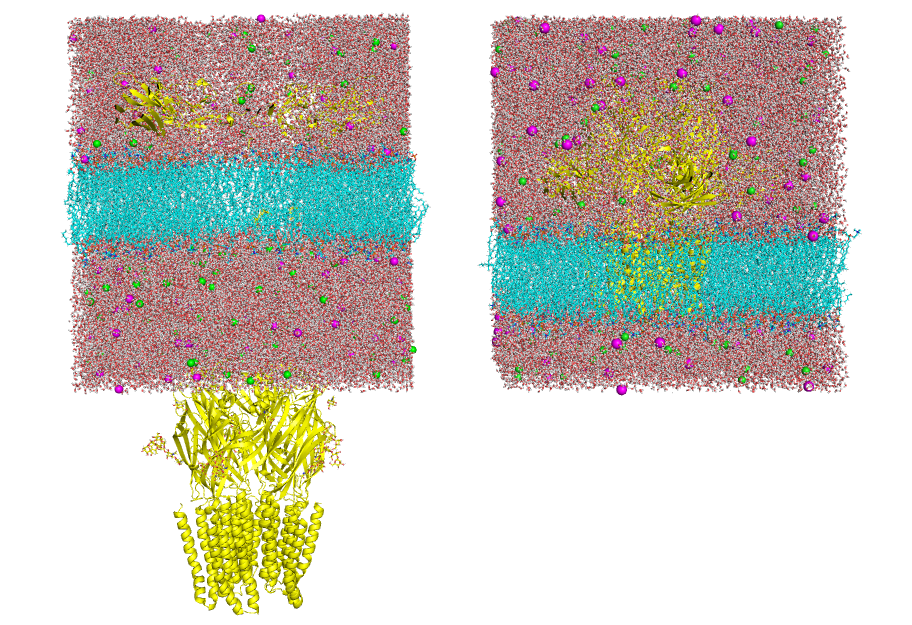
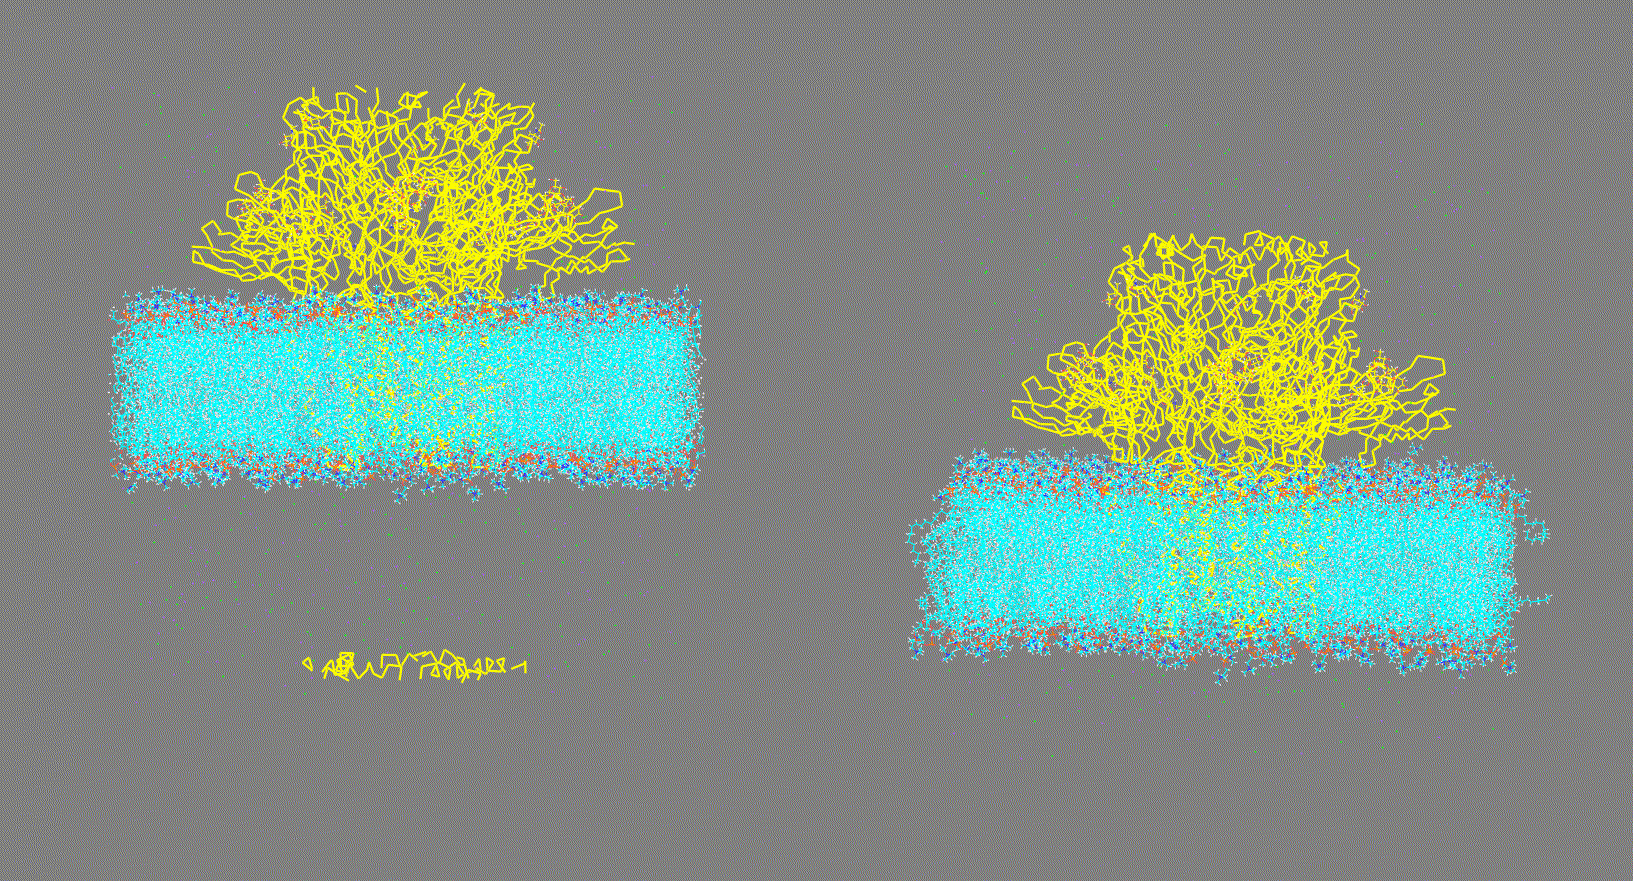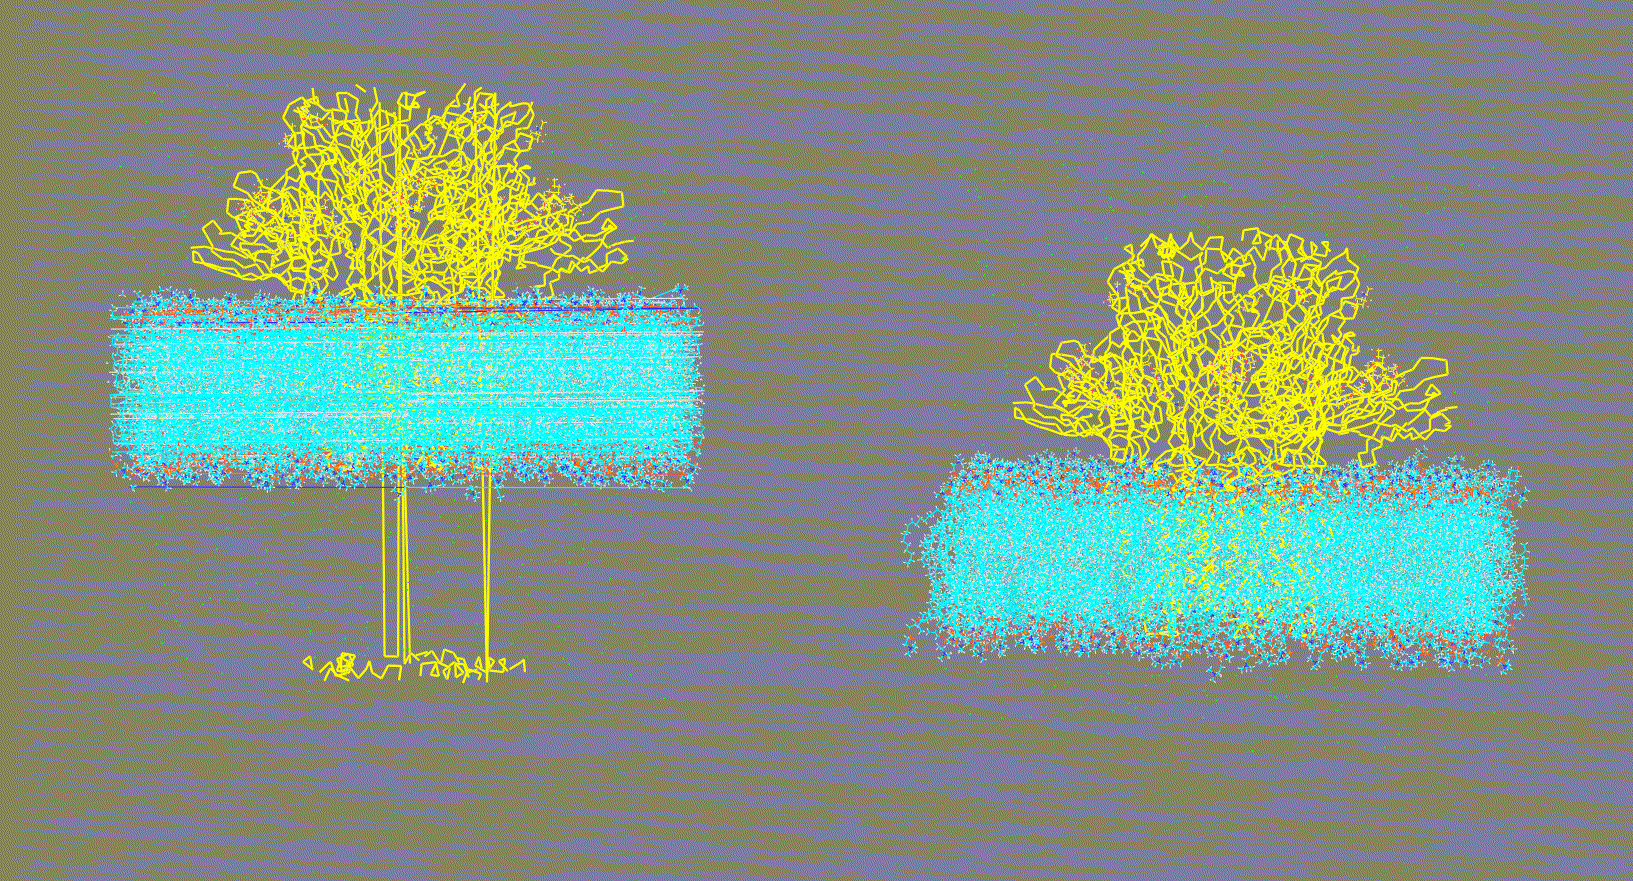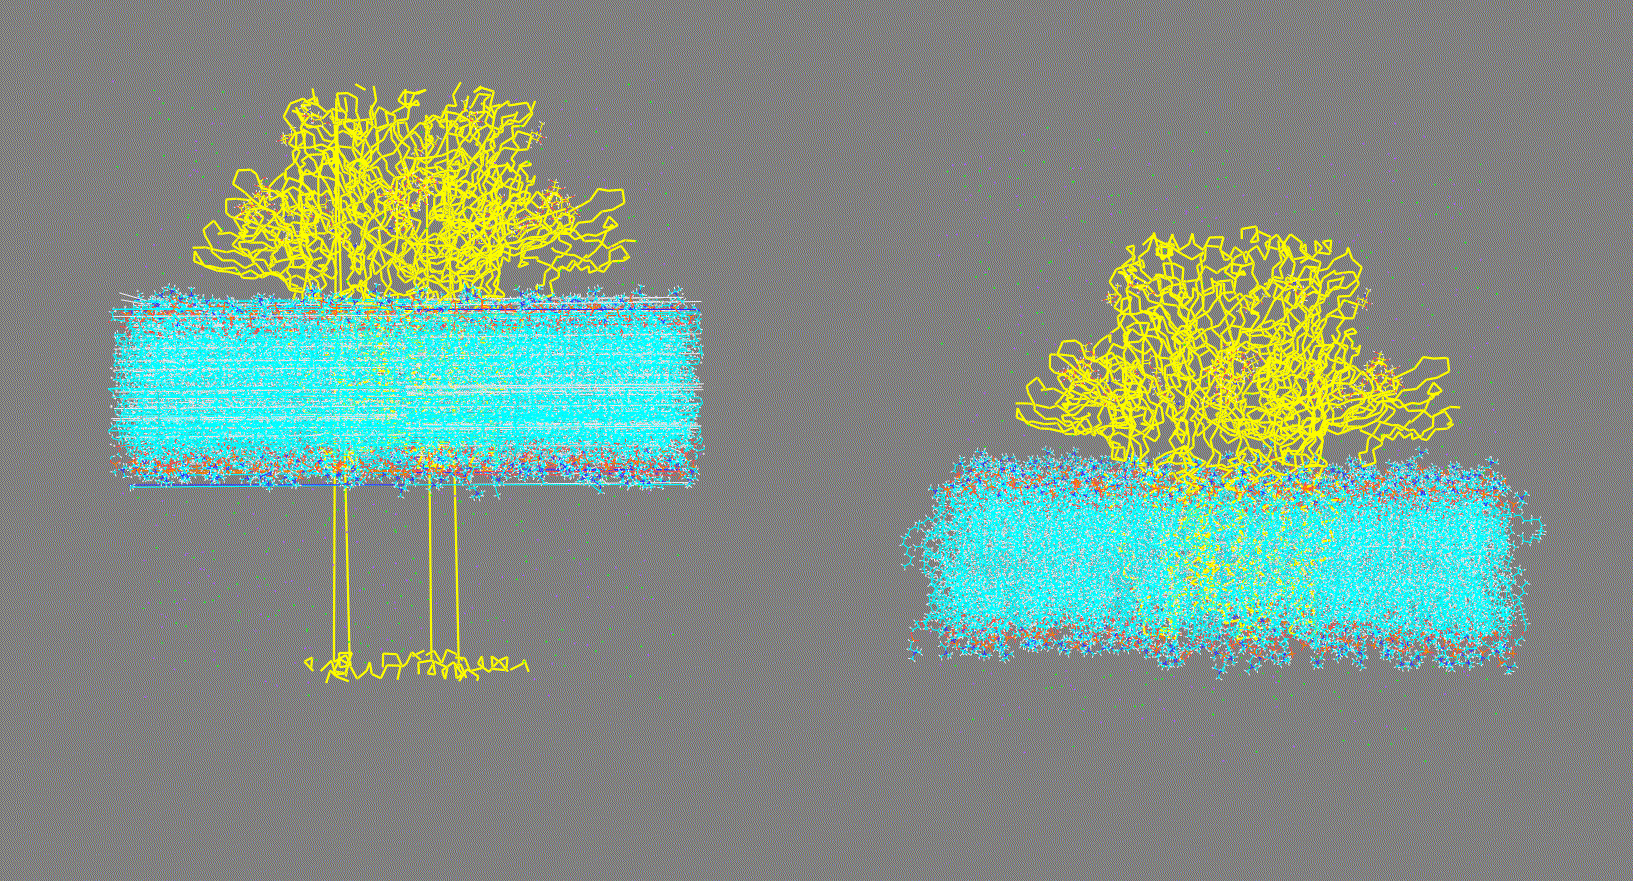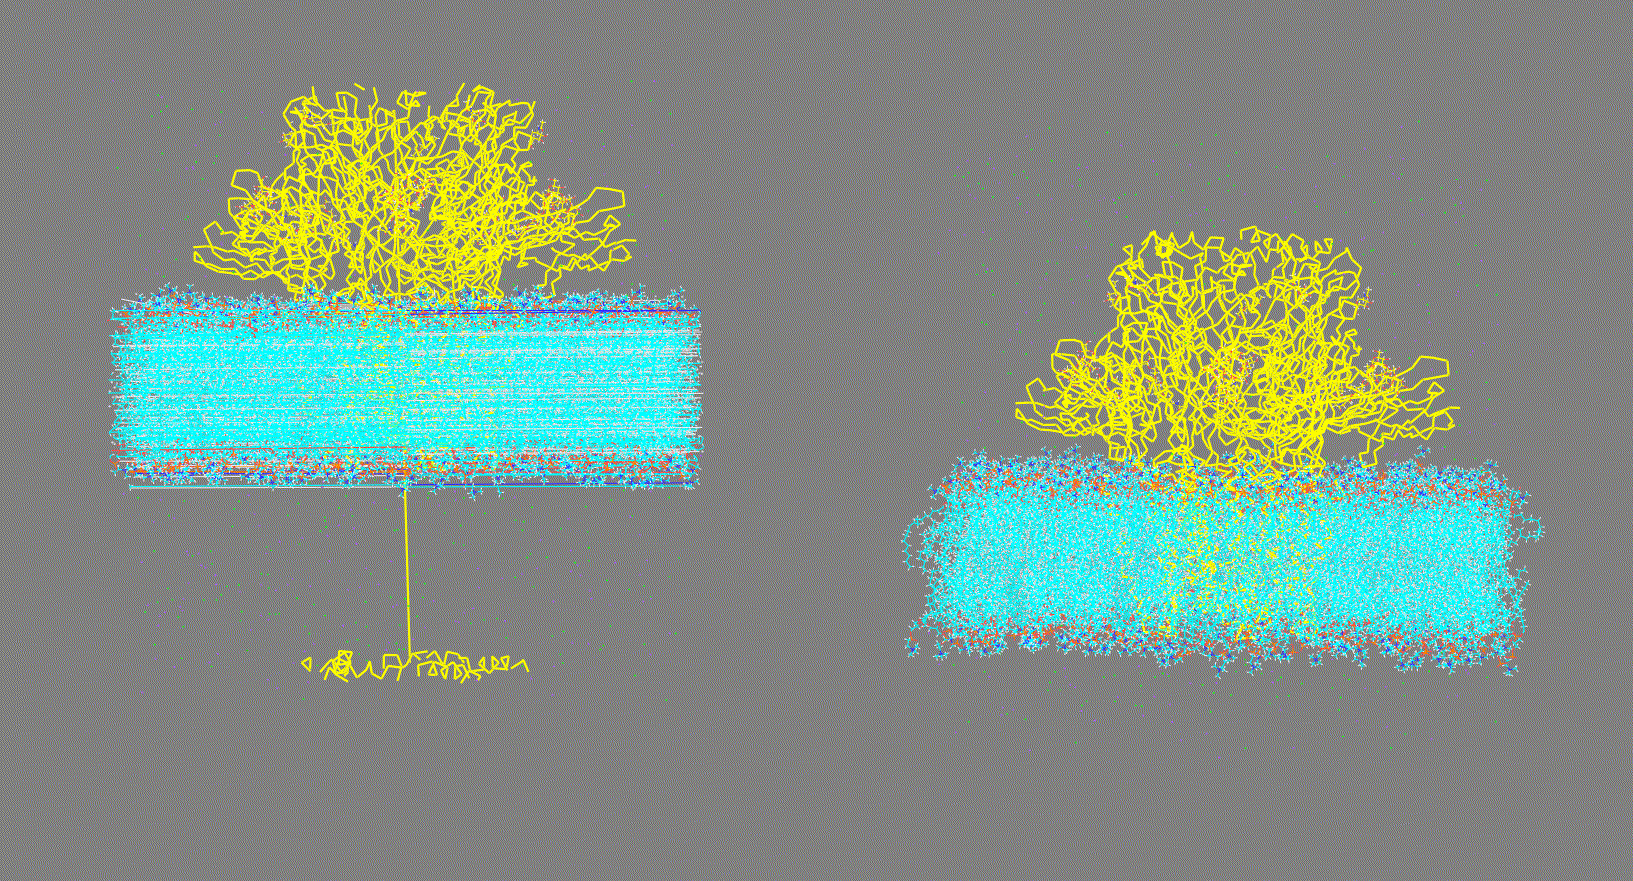
Visualize the structure contained in the structure input file given in the -cs, -rs, or -ls options and make sure it is intact and centered (Figure 1, right). A "broken" structure (Figure 1, left) can produce inconsistent results.
Generate the structure from a *.tpr file:
gmx editconf -f md.tpr -o md.pdb
Remove PBC artifacts from trajectories supplied with -ct, -rt, or -lt
Visualize the trajectory supplied with -ct, -rt, or -lt and make sure periodic-boundary artifacts have been removed (Figure 2, right). An unfitted or broken trajectory (Figure 2, left) can produce inconsistent results.
Steps:
-
Generate a group that contains both molecules
gmx make_ndx -n index.ndx

>1 | 12

>q
Assuming 1 is the receptor and 12 is the ligand. This creates a new group (number 20 in this example)
-
Remove PBC artifacts
gmx trjconv -s md.tpr -f md.xtc -o md_noPBC.xtc -pbc mol -center -n -ur compact center: 20 (created group) output: 0 -
Remove rotation and translation relative to the reference structure (optional)
gmx trjconv -s md.tpr -f md_noPBC.xtc -o md_fit.xtc -n -fit rot+trans fit: 20 (created group) output: 0 -
Inspect the processed trajectory
Make sure that the trajectory is intact and centered (Figure 2, right).
-
If the process is unsuccessful, consider another option such as
-pbc nojump(as suggested here).
Running gmx_MMPBSA
Tip
- Since version 1.4.0 we have fixed the
gmx_MMPBSAinconsistencies when usingMPI. - We currently recommend the use of MPI since the computation time decreases considerably.
Like MMPBSA.py, gmx_MMPBSA uses MPI only for the energy calculations. The remaining steps —such as generating or converting Amber topologies, preparing mutations, and dividing trajectories— run in a single thread (see Figure 3). AmberTools and GROMACS therefore do not need to be compiled with MPI support. The preprocessing time depends on the system and is the same for serial and MPI runs.
Note
Note that gmx_MMPBSA processes, converts, or builds topologies from GROMACS files, so it takes slightly longer than MMPBSA.py at the same stage of the process. However, this is not really significant.
Remember
Make sure that you install the OpenMPI library
sudo apt install openmpi-bin libopenmpi-dev openssh-client
A usage example is shown below:
mpirun -np 2 gmx_MMPBSA -O -i mmpbsa.in -cs com.tpr -ci index.ndx -cg 1 13 -ct com_traj.xtc
#!/bin/sh
#PBS -N nmode
#PBS -o nmode.out
#PBS -e nmode.err
#PBS -m abe
#PBS -M email@domain.edu
#PBS -q brute
#PBS -l nodes=1:surg:ppn=3
#PBS -l pmem=1450mb or > 5gb for nmode calculation

cd $PBS_O_WORKDIR

mpirun -np 3 gmx_MMPBSA -O -i mmpbsa.in -cs com.tpr -ci index.ndx -cg 1 13 -ct com_traj.xtc > progress.log
Danger
When running gmx_MMPBSA with MPI, do not use the GROMACS gmx_mpi executable because it can conflict with mpirun. Use gmx instead. Only mdrun benefits from GROMACS MPI parallelization; the GROMACS tools called by gmx_MMPBSA run in a single thread. See issue 26 for an example.
Warning
The nmode calculations require a considerable amount of RAM. Consider that the total amount of RAM will be:
RAMtotal = RAM1_frame * NUM of Threads
If it consumes all the RAM of the system it can cause crashes, instability or system shutdown!
Note
At a certain level, running RISM in parallel may actually hurt performance, since previous solutions are used as an initial guess for the next frame, hastening convergence. Running in parallel loses this advantage. Also, due to the overhead involved in which each thread is required to load every topology file when calculating energies, parallel scaling will begin to fall off as the number of threads reaches the number of frames.
This version is installed via pip as described above. AMBERHOME variable must be set, or it will quit with an error. An example command-line call is shown below:
gmx_MMPBSA -O -i mmpbsa.in -cs com.tpr -ci index.ndx -cg 1 13 -ct com_traj.xtc
You can find test files on GitHub.
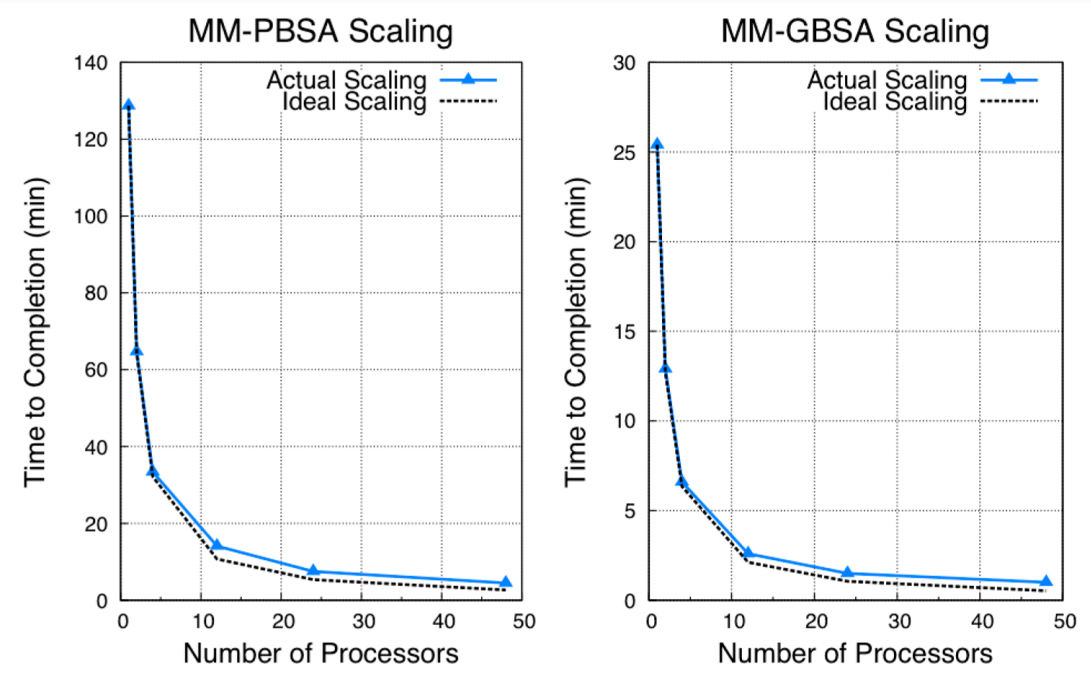
Figure 3. MPI benchmark description from MMPBSA.py paper. MMPBSA.py scaling comparison for MM-PBSA and MM-GBSA calculations on 200 frames of a 5910-atom complex. Times shown are the times required for the calculation to finish. Note that MM-GBSA calculations are ∼5 times faster than MM-PBSA calculations. All calculations were performed on NICS Keeneland (2 Intel Westmere 6-core CPUs per node, QDR infiniband interconnect)
Created: January 27, 2022 07:53:46